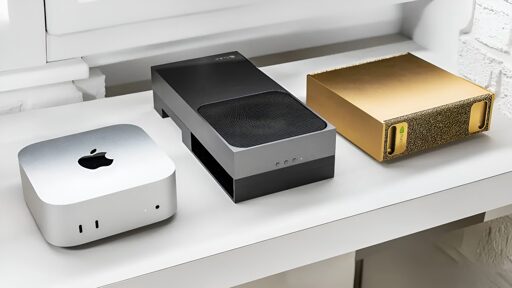
eicker@lemmy.world to Technology@lemmy.worldEnglish · 1 month agoOpenAI Hoarding Tens Of Thousands Of Apple Mac mini And Mac Studio Devices, As ASUS And MSI Burn Through Their Entire First Batch Of NVIDIA RTX Spark Chip And Beg For More.wccftech.comexternal-linkmessage-square18linkfedilinkarrow-up1122arrow-down10
arrow-up1122arrow-down1external-linkOpenAI Hoarding Tens Of Thousands Of Apple Mac mini And Mac Studio Devices, As ASUS And MSI Burn Through Their Entire First Batch Of NVIDIA RTX Spark Chip And Beg For More.wccftech.comeicker@lemmy.world to Technology@lemmy.worldEnglish · 1 month agomessage-square18linkfedilink
minus-squaredeleted@lemmy.worldlinkfedilinkEnglisharrow-up11·1 month agoLocal 27b models are good enough for most tasks. Can’t wait to buy one of these from Ebay for 10% of the price next year.
minus-squaregdog05@lemmy.worldlinkfedilinkEnglisharrow-up5·1 month agoAnd that’s really why they’re hoarding them.
minus-squareLydia_K@lemmy.worldlinkfedilinkEnglisharrow-up4arrow-down1·1 month agohttps://github.com/AtomicBot-ai/atomic-llama-cpp-turboquant I’m running gwen 3.6 with 131k context window on a 3090, it’s fast enough and about as good as pay to play Claude at work.
minus-squareChee_Koala@lemmy.worldlinkfedilinkEnglisharrow-up2·edit-21 month agoAny 27b Model you can currently recommend for a 16gb AMD ? Mostly coding tasks but not exclusively.
minus-squareabcdqfr@lemmy.worldlinkfedilinkEnglisharrow-up3·1 month agoThere is a way. There was a post yesterday on exactly this, let me find it… https://lemmy.world/post/51283416
minus-squaredeleted@lemmy.worldlinkfedilinkEnglisharrow-up2arrow-down1·1 month agoFor your hardware, the VRam is not enough to run 27b but, I’d recommend Qwen 3.5 9b for image / text to text. And I’m planning to experiment with Qwen 3.8 9b for text to text. 4_k_m quantization is the sweet spot for performance and ram usage. Also, I find Llama cpp is better than Ollama in terms of performance.


Local 27b models are good enough for most tasks.
Can’t wait to buy one of these from Ebay for 10% of the price next year.
And that’s really why they’re hoarding them.
https://github.com/AtomicBot-ai/atomic-llama-cpp-turboquant
I’m running gwen 3.6 with 131k context window on a 3090, it’s fast enough and about as good as pay to play Claude at work.
Any 27b Model you can currently recommend for a 16gb AMD ? Mostly coding tasks but not exclusively.
There is a way. There was a post yesterday on exactly this, let me find it… https://lemmy.world/post/51283416
Thx I’ll give this a try!
For your hardware, the VRam is not enough to run 27b but, I’d recommend Qwen 3.5 9b for image / text to text.
And I’m planning to experiment with Qwen 3.8 9b for text to text.
4_k_m quantization is the sweet spot for performance and ram usage.
Also, I find Llama cpp is better than Ollama in terms of performance.
Thx for the tips!